


Новое исследование от AstraZeneca:
Do humans and large language models agree on the quality of synthesis plans? 🔥
https://doi.org/10.1039/d6dd00266h
📕Digital Discovery (IF=7.1)
Do humans and large language models agree on the quality of synthesis plans? 🔥
https://doi.org/10.1039/d6dd00266h
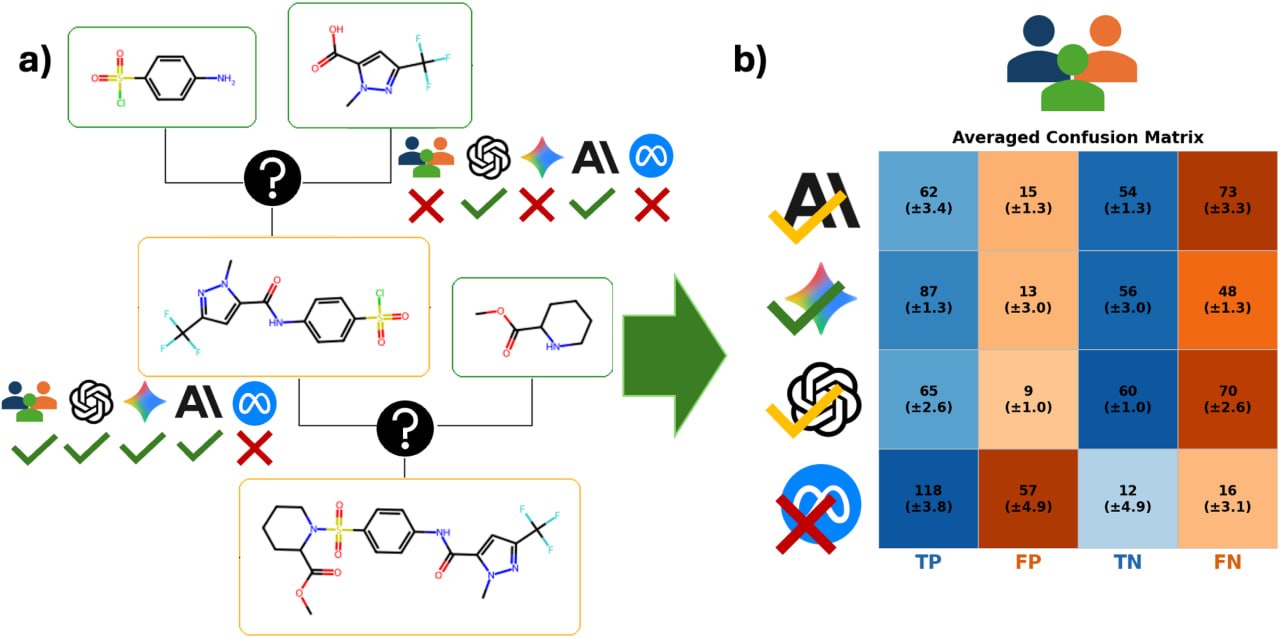
Here, we investigated whether LLMs could mimic human experts on the challenging task of assessing retrosynthetic path feasibility in routes generated by a popular computer-aided synthesis planning tool (AiZynthFinder).
We evaluated the agreement between LLMs and expert chemists on holistic evaluations of the proposed routes as well as the individual chemical reactions in them. We used four frontier LLMs, three proprietary models and one open-source model (Claude Opus 4.8, GPT-5.5, Llama 3.1 70B, and Gemini 3.1 Pro) and employed 17 expert chemists to grade 50 retrosynthetic paths.
We found that, when provided with clearly defined reaction-evaluation categories, human experts tended to converge in their assessments. Among the evaluated models, Gemini 3.1 Pro achieved the highest agreement with the human majority vote. GPT-5.5 and Claude Opus 4.8 were comparatively more pessimistic, whereas Llama 3.1 70B showed a pronounced optimistic bias.
📕Digital Discovery (IF=7.1)